Meta Says Prometheus Phase One Trained Muse Wonder, Targets 1 Million GPUs
Summary
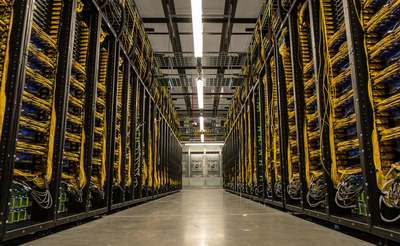
Meta says the first phase of Prometheus, its gigawatt-scale supercluster in New Albany, Ohio, is complete and trained its Muse foundational models, including Muse Wonder. The company claims more than 85% goodput on pre-training runs and plans to scale to roughly 1 million GPUs.
Key Points
- Meta says firmware fixes lift mean time between interruptions to more than 54,000 GPU hours, up from roughly 47,000.
- Meta's Catalina racks pair each Blackwell GPU with a Grace CPU and two 400G ConnectX-7 NICs, giving 800G of scale-out per GPU.
- Meta provisions 523 NVL72 racks, about 13% above the active GPU footprint, for a 32,768-GPU training run.