Ant Group and vLLM Claim 43% Throughput Gain from Humming Kernels on H20
Summary
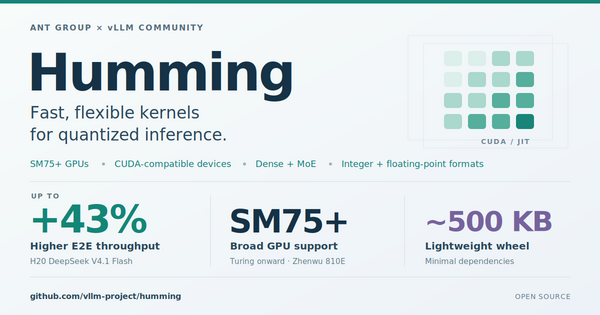
Ant Group and the vLLM community open-source Humming, a kernel library for quantized inference that supports NVIDIA GPUs from Turing onward and T-Head's Zhenwu 810E. Kernels compile just in time from shared CUDA components. The groups claim switching DeepSeek-V4.1-Flash MoE execution to Humming's W4A8 path on eight H20 GPUs raises throughput 14% to 43%.
Key Points
- Ant Group and the vLLM community report mean time to first token falls about 25% to 32% on eight H20 GPUs.
- The groups measure compiling one W4A16 kernel on an H200 with CUDA 13.4 at 1.82 seconds versus 23.35 seconds for CUTLASS NVCC.
- Humming ships as a CUDA dependency starting with vLLM 0.29.0, with a wheel of about 500 KB.