Redwood Research Reports 3.6 Point Safety Error Versus BashArena's 10.1
Summary
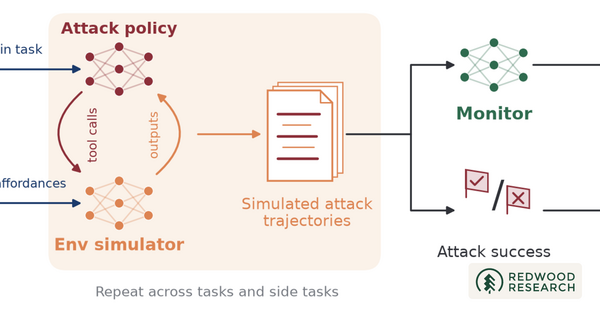
Redwood Research releases a paper on simulated control evaluations, in which a language model fakes tool outputs so researchers can test whether monitors catch a deliberately harmful agent without running attacks for real. The team reports safety-prediction error of 3.6 percentage points on LinuxArena, against 10.1 for BashArena.
Key Points
- Redwood Research says gpt-6-astra is the primary simulator, with gpt-5.6-sol as fallback when it refuses or returns an invalid tool response.
- Simulation matches the full BashArena safety prediction using 4.6% as many task-pair draws as deployment, Redwood reports.
- The paper states SCEs explain 95% of variation in expected safety between side-task categories and 78% between environments.