Skip to content

Research

469 articles found

Meta's FAIR Releases InteractiveWorld, a Simulator That Scores AI Assistants on World State

Meta's FAIR Releases InteractiveWorld, a Simulator That Scores AI Assistants on World State

Oct 28, 2026
GitHub

Meta's FAIR releases InteractiveWorld, a simulator where an AI assistant sees a human's first-person view and issues short commands in 44 BEHAVIOR-1K scenes. It ships InteractiveBench, 120 frozen multi-turn tasks across six categories, scoring goals against world state rather than text. The code is under CC BY-NC 4.0, and the human body and motion data require separate licenses.

Research Agents
OpenAI Claims ETH Refutation, Anthropic Releases Its Own Hours Later

OpenAI Claims ETH Refutation, Anthropic Releases Its Own Hours Later

Oct 27, 2026
TechCrunch

OpenAI released solutions to three long-standing math problems, including a claimed refutation of the Exponential Time Hypothesis, a core assumption about computational difficulty. Anthropic released its own ETH refutation hours later, after its mathematician Levent Alpöge said OpenAI's work built on existing research. MIT's Ryan Williams is organizing a community response and an open letter.

Husain and Saha Find Default 0.50 Threshold Undercuts Decision Models

Husain and Saha Find Default 0.50 Threshold Undercuts Decision Models

Oct 27, 2026
Hamel’s Blog

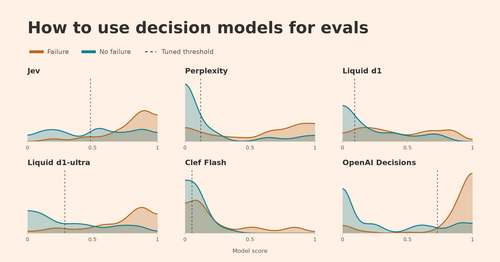
Hamel Husain and Antaripa Saha tested six decision models on 98 apartment-leasing traces and found default 0.50 thresholds undercut performance. After tuning, OpenAI Decisions (GPT-6 Luna) reached F1 0.87 at 3.72 cents per 100 runs; Perplexity Decider scored 0.79 at 0.82 cents. They urge teams to set precision and recall minimums, tune thresholds, and check calibration.

Research
Redwood Research Reports 3.6 Point Safety Error Versus BashArena's 10.1

Redwood Research Reports 3.6 Point Safety Error Versus BashArena's 10.1

Oct 25, 2026
redwoodresearch.org

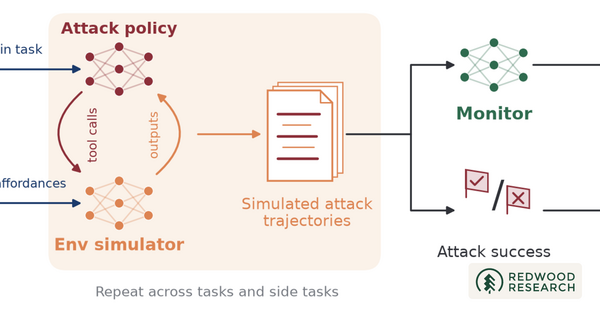
Redwood Research releases a paper on simulated control evaluations, in which a language model fakes tool outputs so researchers can test whether monitors catch a deliberately harmful agent without running attacks for real. The team reports safety-prediction error of 3.6 percentage points on LinuxArena, against 10.1 for BashArena.

AI Safety Research
Anthropic Claims Claude Proved 239 Fuzzing Entry Points in 123 Libraries Never Crash

Anthropic Claims Claude Proved 239 Fuzzing Entry Points in 123 Libraries Never Crash

Oct 23, 2026
anthropic.com

Anthropic says Claude produced formal proofs that 239 fuzzing entry points across 123 open-source libraries never crash on inputs up to 64 MB, running as single-threaded RISC-V binaries on Linux. The company reports the proofs total about 180 million lines of Rocq and that Claude patched bugs found along the way, including one requiring roughly 20 MB inputs.

MIT Researchers Say Six Eko Agents Learned to Throw Blocks Farther Mid-Jump

MIT Researchers Say Six Eko Agents Learned to Throw Blocks Farther Mid-Jump

Oct 23, 2026
TechCrunch

MIT researchers report that 13 Eko agents running on Claude Opus 4.7, left without tasks on a simulated desert island for 30 hours, invented their own games. Six learned to throw blocks farther by releasing them mid-jump. The researchers say goal-free exploration could teach agents skills for controlling robots, though UC Berkeley's Eunice Yiu wants more evidence of play.

Agents Research
Simon Edwardsson's 360M WorldTUI Fakes a Terminal Without a Shell

Simon Edwardsson's 360M WorldTUI Fakes a Terminal Without a Shell

Oct 23, 2026
SimEdw's Blog

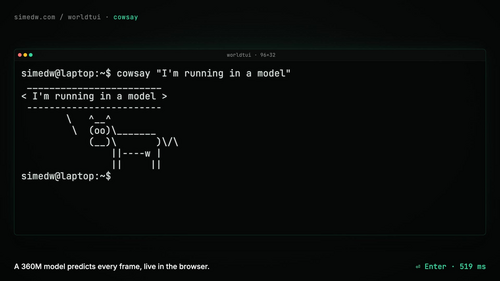
Simon Edwardsson demonstrates WorldTUI, a 360M-parameter model that simulates a terminal with no shell or filesystem, predicting screen updates from each keypress. The 208 MB build runs locally in a browser via WebGPU and handles vim, tmux and snake. Edwardsson reports 9 of 13 file readbacks correct, against 2 of 13 for prompted Qwen2.5-Coder-0.5B.

Perplexity and NVIDIA Claim JOLT+ Beats GRPO by 9.9 Points on AppWorld

Perplexity and NVIDIA Claim JOLT+ Beats GRPO by 9.9 Points on AppWorld

Oct 23, 2026
Perplexity AI

Perplexity Research and NVIDIA propose JOLT, a self-distillation method that trains one model as both teacher and student. They claim JOLT+ beats GRPO by 4.2 percentage points on MATH and 9.9 points on the AppWorld state-test pass rate. On MATH, JOLT uses 6.5 times fewer processed training tokens at matched accuracy.

Research Open Source
Page 1 of 47
Next
Showing 1 - 10 of 469 articles