Skip to content

Research

466 articles found

METR Agrees Anthropic Misalignment Risk Is Low, Credits Limited Capability

METR Agrees Anthropic Misalignment Risk Is Low, Credits Limited Capability

Oct 21, 2026
metr.org

METR reviews Anthropic's August 2026 risk report and agrees misalignment risk from covered models, including Mythos 5, is low, but says that reflects limited capabilities rather than alignment training or monitoring. METR's Nikola Jurkovic, Tim Hua and Beth Barnes say Anthropic's covert-capability benchmarks poorly test evasion of its real monitoring system, and cite incidents that undercut the report's argument.

Mercor Says 90% of US Work Hours Lack AI Benchmark Coverage

Mercor Says 90% of US Work Hours Lack AI Benchmark Coverage

Oct 19, 2026
mercor.com

Mercor maps 29 AI benchmarks against 923 O*NET occupations and reports that only 208 have a task with at least 5 benchmark prompts. The company estimates 90% of American working hours go to tasks with little or no benchmark coverage, and 6 of 22 job families have none.

Labor & Jobs Research
HazyResearch Claims NCM Generates Text 9 to 31 Times Faster Than Diffusion Baselines

HazyResearch Claims NCM Generates Text 9 to 31 Times Faster Than Diffusion Baselines

Oct 18, 2026
GitHub

HazyResearch publishes NCM, a two-stage text generation framework whose coarse-to-fine decoder predicts token hierarchies in parallel, with authors claiming 9-31x faster generation than strong diffusion baselines at matching quality. Code, checkpoints, and tokenized datasets are released under the MIT license on Hugging Face, requiring Python 3.10 or newer and a CUDA-capable PyTorch install.

Research Open Source
Yingru Li Argues the Policy Gradient Is a Covariance and the Fisher a Variance

Yingru Li Argues the Policy Gradient Is a Covariance and the Fisher a Variance

Oct 16, 2026
Yingru Li

Yingru Li argues in Part 1 of a three-part theory series that the expected policy gradient is a covariance and the Fisher a variance, capping the gradient for any reward and explaining why post-training updates stay sparse. Li cites measurements that the top 1% of coordinates by Fisher hold 47.40% of the top 1% by gradient magnitude.

Research
Artificial Analysis Says GPT-6 Astra Leads Robot Arm Test at 69

Artificial Analysis Says GPT-6 Astra Leads Robot Arm Test at 69

Oct 15, 2026
artificialanalysis.ai

Artificial Analysis releases AA-Robotics v0.1, a research preview testing frontier language models on controlling a 6-axis robot arm across eight tabletop tasks. GPT-6 Astra leads with a score of 69, averaging 30 minutes and $16.36 per task. The firm says models run about 100 times slower than humans.

Robotics Research
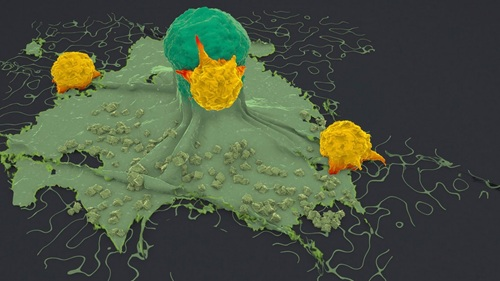
MD Anderson's SPACER Finds Mucins May Block T Cells from Tumors

MD Anderson's SPACER Finds Mucins May Block T Cells from Tumors

Oct 15, 2026
Florida Hospital News and Healthcare Report

Researchers at MD Anderson and Texas collaborators report SPACER, an AI model using spatial transcriptomics, decodes signals that draw or repel immune cells. Tested on 37 cancer datasets, the model performed four to 21 times better than existing methods at finding recruitment signals. They say mucins may block T cells, linked to poorer checkpoint inhibitor responses.

Healthcare Research Science
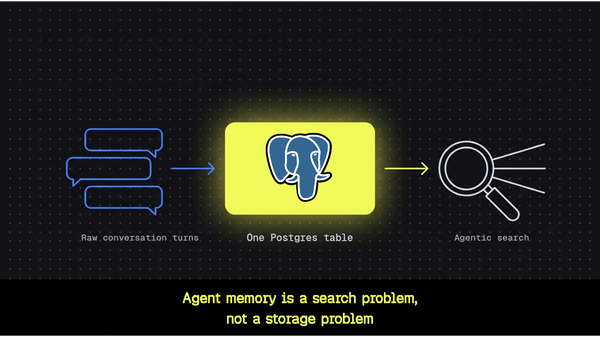
Tiger Data Reports F1 0.665 on LoCoMo with a Single Postgres Table

Tiger Data Reports F1 0.665 on LoCoMo with a Single Postgres Table

Oct 15, 2026
Tiger Data Blog

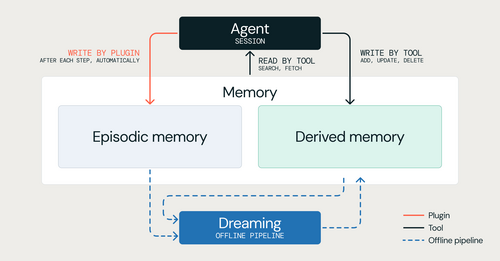
Tiger Data's Matvey Arye reports that storing raw conversation turns in one Postgres table and giving an agent three MCP search tools scores F1 0.665 on LoCoMo with Claude Sonnet, above Omni-SimpleMem's reported 0.613. Dropping LLM-extracted atomic facts did not lower F1 and cut about 50% of ingestion time, the company says.

OpenAI Says One Agent Query Solves More Than 300 Open Math Problems

OpenAI Says One Agent Query Solves More Than 300 Open Math Problems

Oct 13, 2026
secondthoughts.ai

Attendees at the Golden Gate Institute for AI's annual Curve conference in Berkeley say timelines to superintelligence and loss of control feel uncomfortably short. Helen Toner of CSET said long timelines aren't what they used to be. OpenAI reports solving over 300 open math problems with one agent query, about three hours of compute each.

AI Safety Agents Research
Previous
Page 2 of 47
Next
Showing 11 - 20 of 466 articles