Husain and Saha Find Default 0.50 Threshold Undercuts Decision Models
Summary
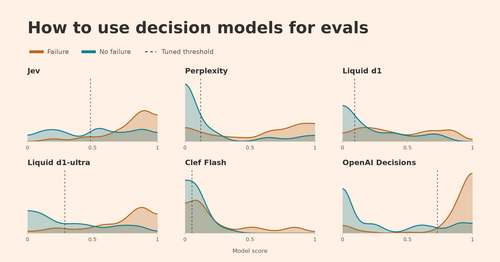
Hamel Husain and Antaripa Saha tested six decision models on 98 apartment-leasing traces and found default 0.50 thresholds undercut performance. After tuning, OpenAI Decisions (GPT-6 Luna) reached F1 0.87 at 3.72 cents per 100 runs; Perplexity Decider scored 0.79 at 0.82 cents. They urge teams to set precision and recall minimums, tune thresholds, and check calibration.
Key Points
- Husain and Saha label 61 of the 98 traces as known failures, leaving 37 without a labeled failure.
- Perplexity Decider misses the 80 percent precision and recall minimum in 36 of 100 training splits, OpenAI never misses.
- Cloudflare Clef Flash puts one trace group near 8 percent predicted failure risk, yet 60 percent of those traces hold failures.